Review-based Understanding & Mining of Online Reputation
NLP/LLM – Sentiment Analysis – Customer Experience – Explainable AI
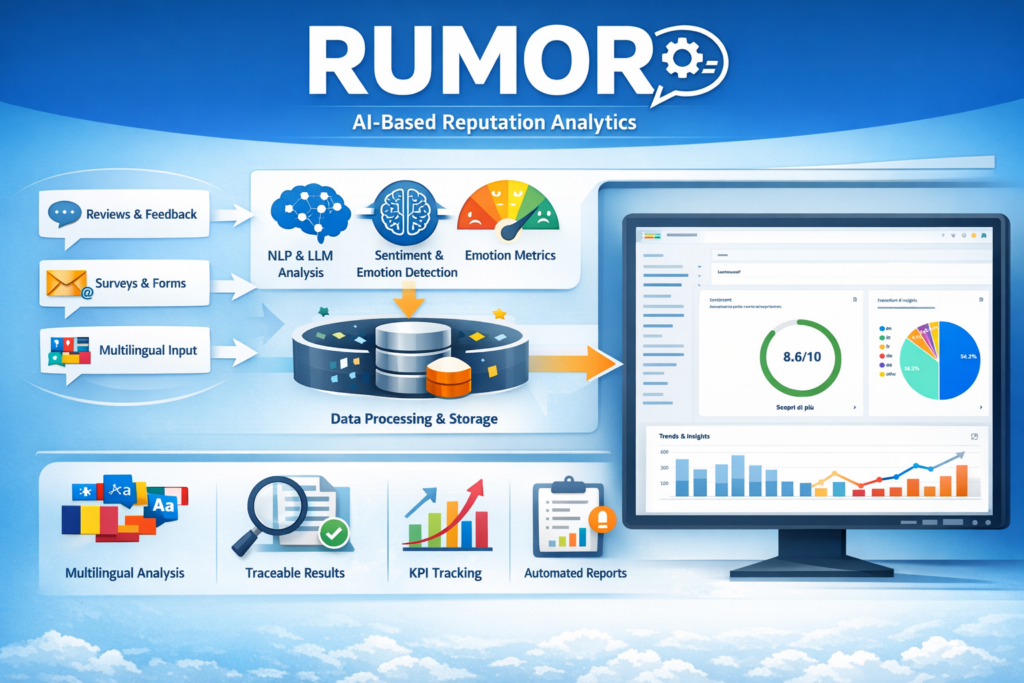
RUMOR is a modular, AI-backed pipeline for mining reputation signals from unstructured user-generated text (reviews, survey free-text, contact-form messages, post-visit feedback) collected across heterogeneous channels and markets. The system implements an end-to-end workflow that covers ingestion, language detection and normalization, text pre-processing, document- and sentence-level inference, structured storage, and user-facing analytics.
At the core, RUMOR combines modern NLP/LLM-based components with a controlled post-processing layer to produce operationally reliable outputs. It computes continuous sentiment scores (configurable at review, sentence, or aspect level), performs aspect/theme extraction to identify recurring drivers of satisfaction and dissatisfaction, and supports fine-grained affect detection (emotion categories beyond binary polarity) to capture patterns such as frustration, delight, disappointment, or reassurance. The pipeline is designed to handle multilingual inputs and to preserve “evidence links” between aggregated indicators and the originating text spans, enabling traceability and auditability of computed metrics.
RUMOR persists normalized outputs in a structured datastore with versioned schemas, enabling reproducible analyses and longitudinal monitoring. This supports time-series tracking of reputation KPIs, cross-channel and cross-market comparisons, segmentation by customer/visitor type when metadata is available, and automated reporting (e.g., trends, emerging topics, alerting on rising negative drivers). The analytics layer exposes configurable filters and comparative views aimed at non-expert users, while the backend can export machine-readable outputs (e.g., CSV/JSON) for integration with dashboards or downstream decision-support modules.
Contacts:
Prof. Luca Pulina